Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
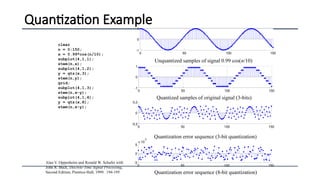
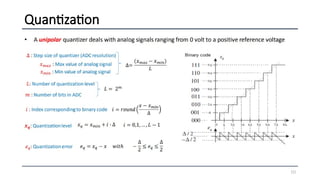
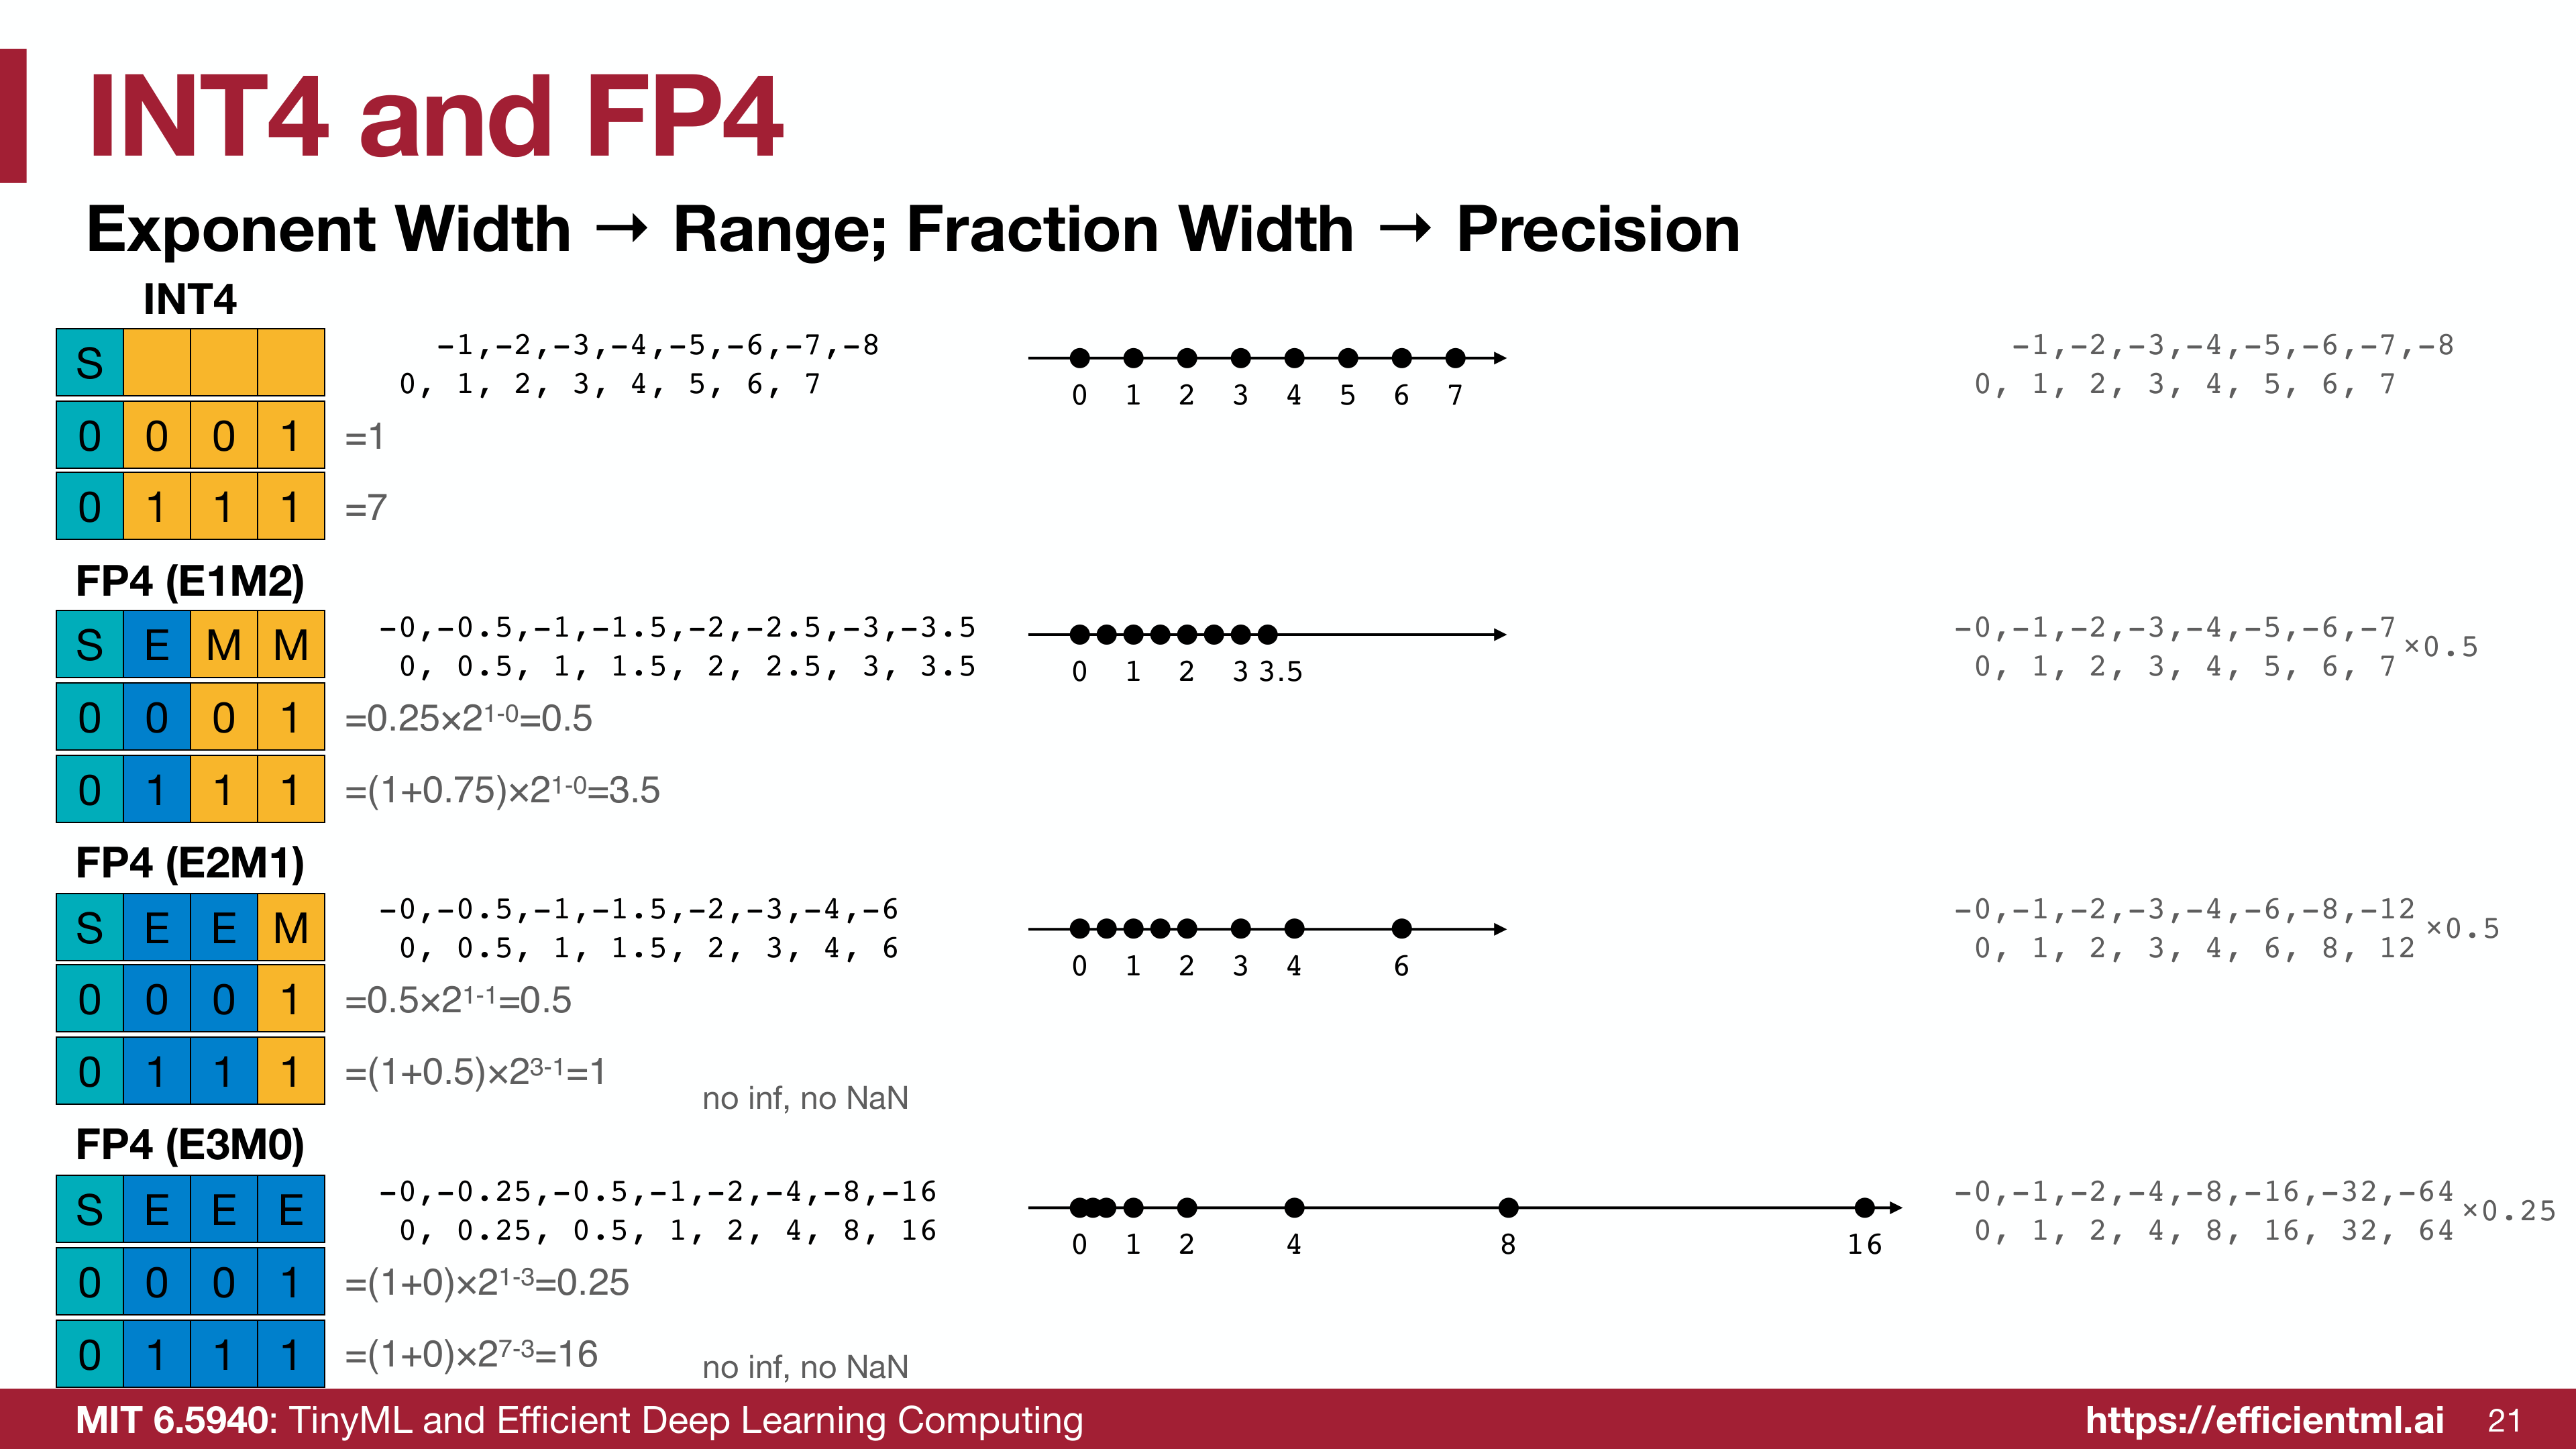
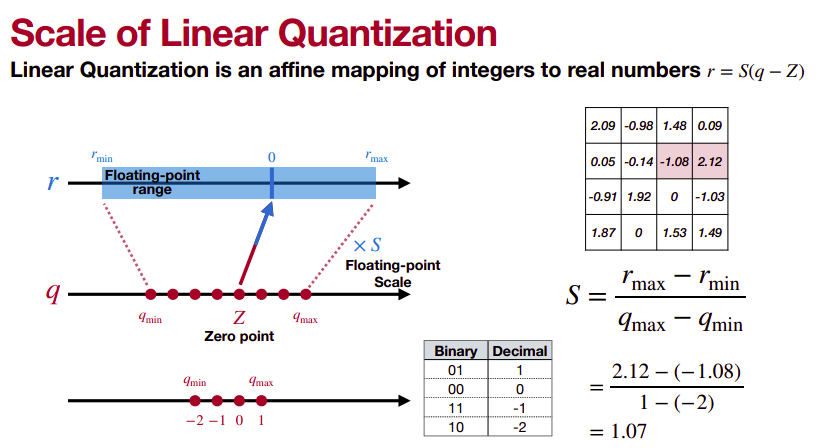
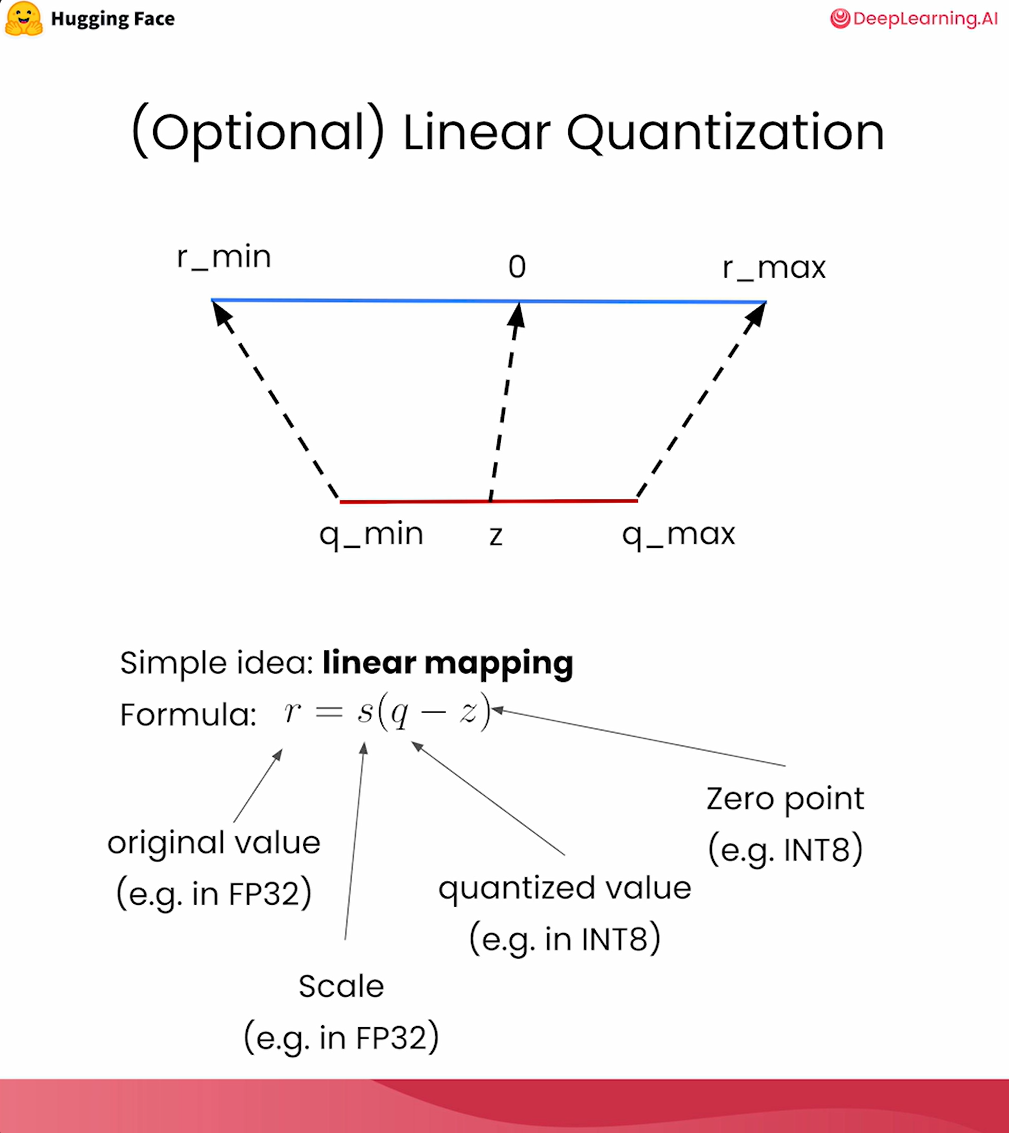
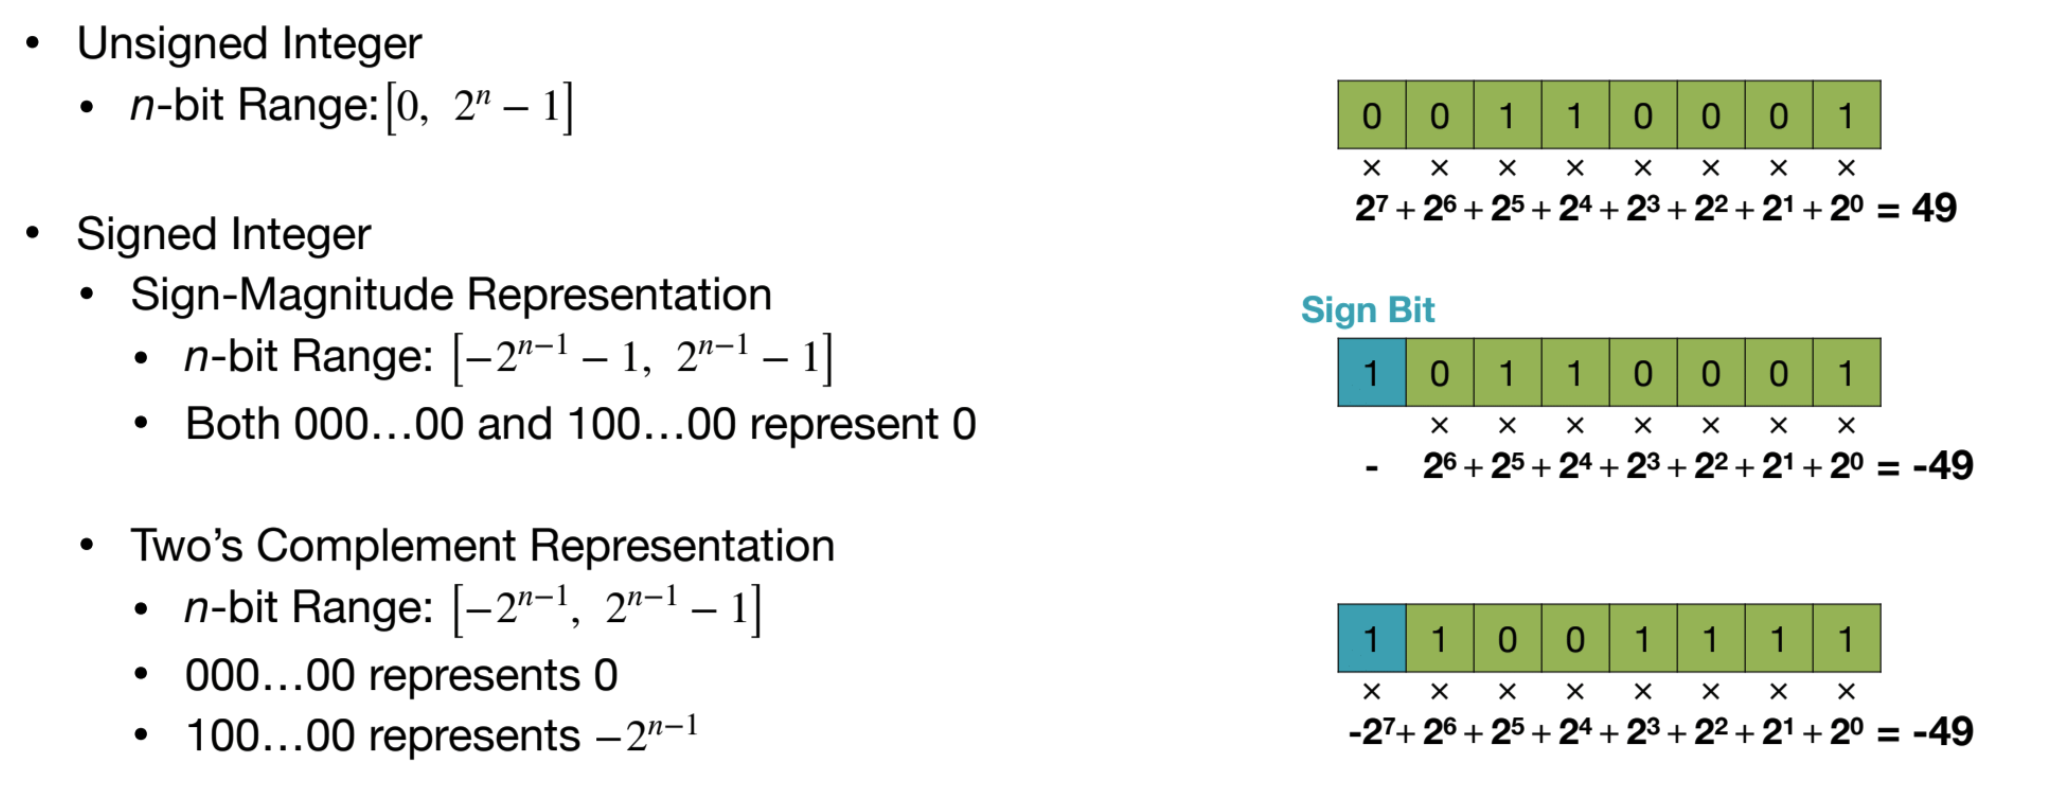
Lecture Number 4 Quantization .pptx
INT vs FP Data Types for Quantization - by Benjamin Marie
(a) The quantization error ϵ int introduced at the end of the ...
Integer-Only CNNs with 4 Bit Weights and Bit-Shift Quantization Scales ...
4-bit LLM training and Primer on Precision, data types & Quantization
Understanding Int4 scalar quantization in Lucene - Search Labs
Quantization Part 1: Understanding Numeric Data Types | SriHarsha ...
[论文评述] FireQ: Fast INT4-FP8 Kernel and RoPE-aware Quantization for LLM ...
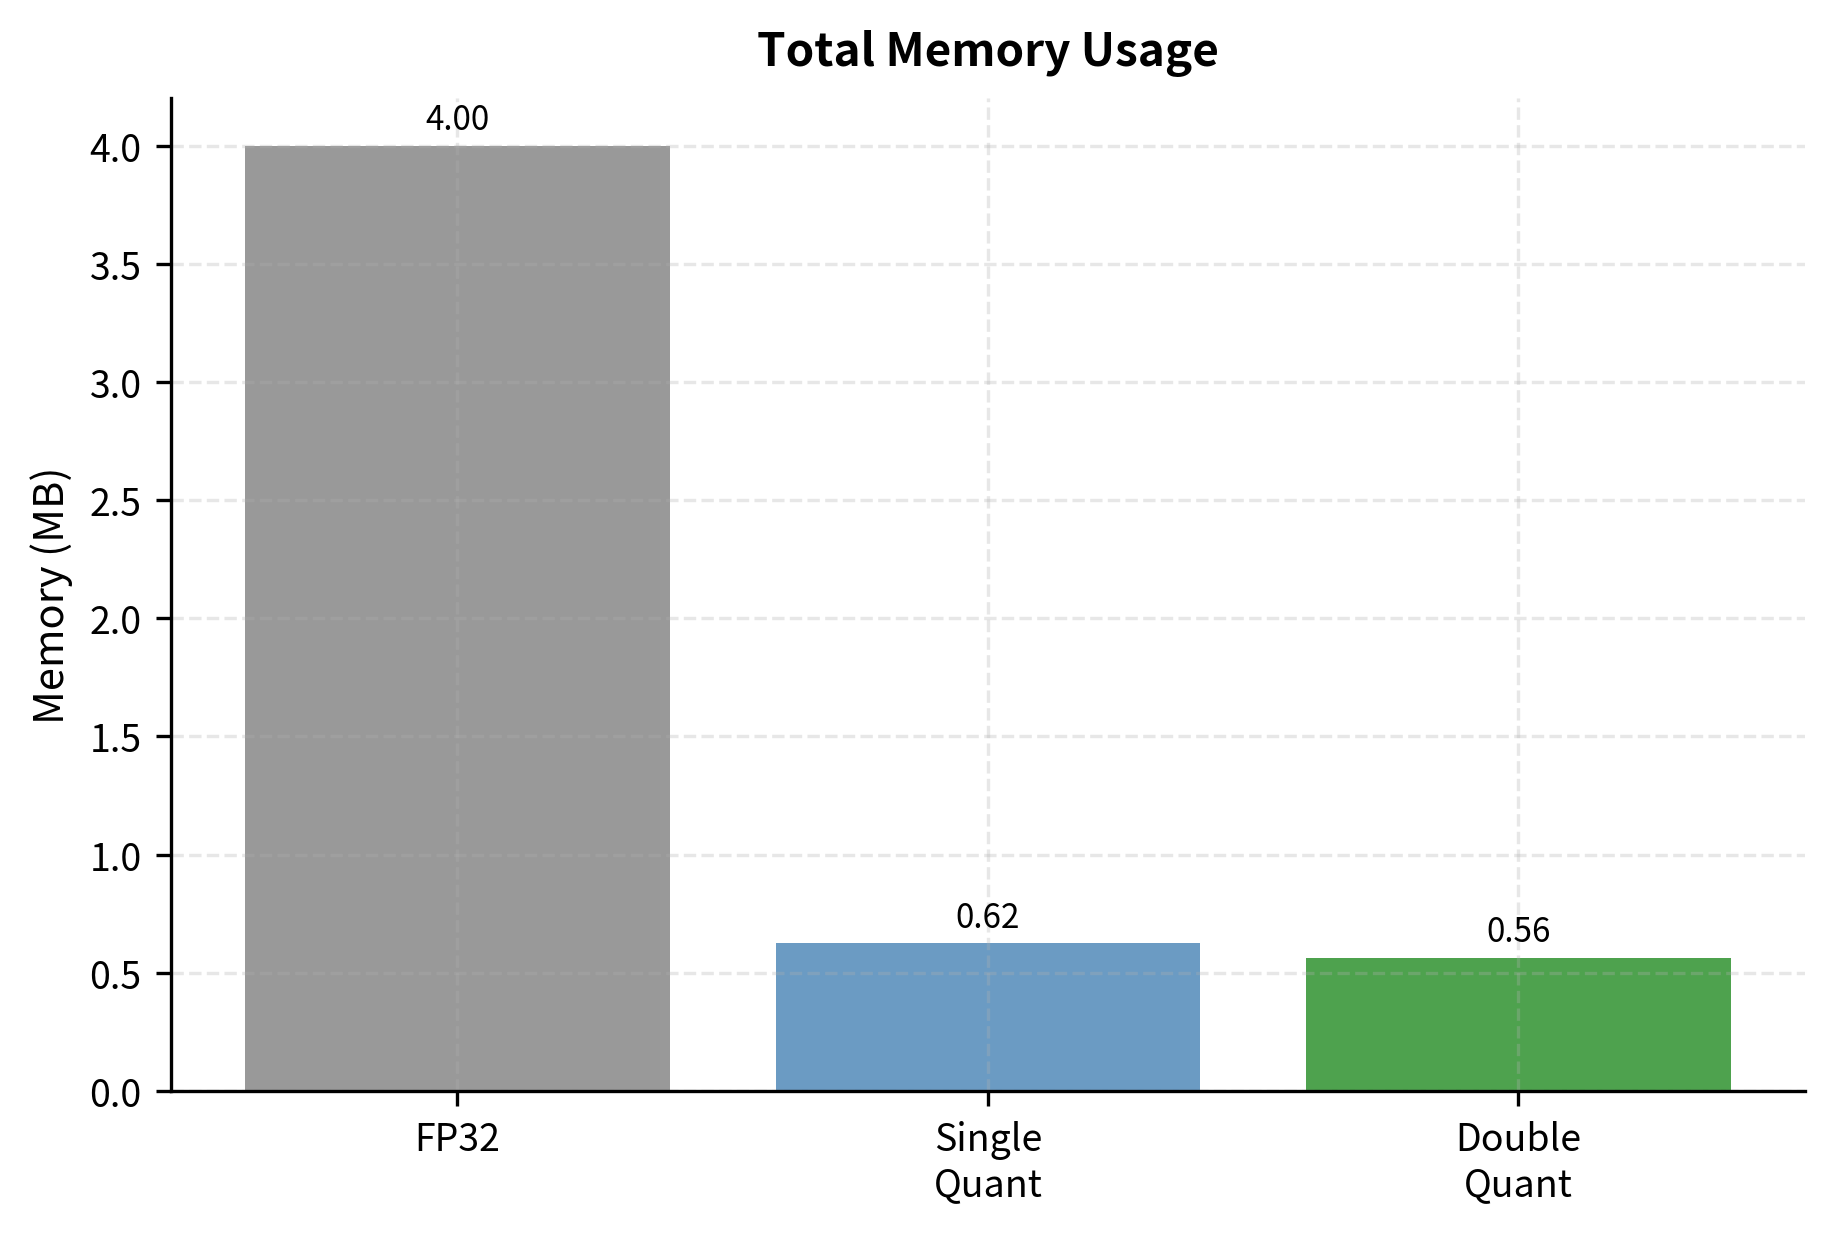
QLoRA: 4-Bit Quantization for Memory-Efficient LLM Fine-Tuning ...
A Hands-On Walkthrough on Model Quantization - Medoid AI
A Survey of Quantization Methods for Efficient Neural Network Inference ...
[论文评述] SAW-INT4: System-Aware 4-Bit KV-Cache Quantization for Real ...
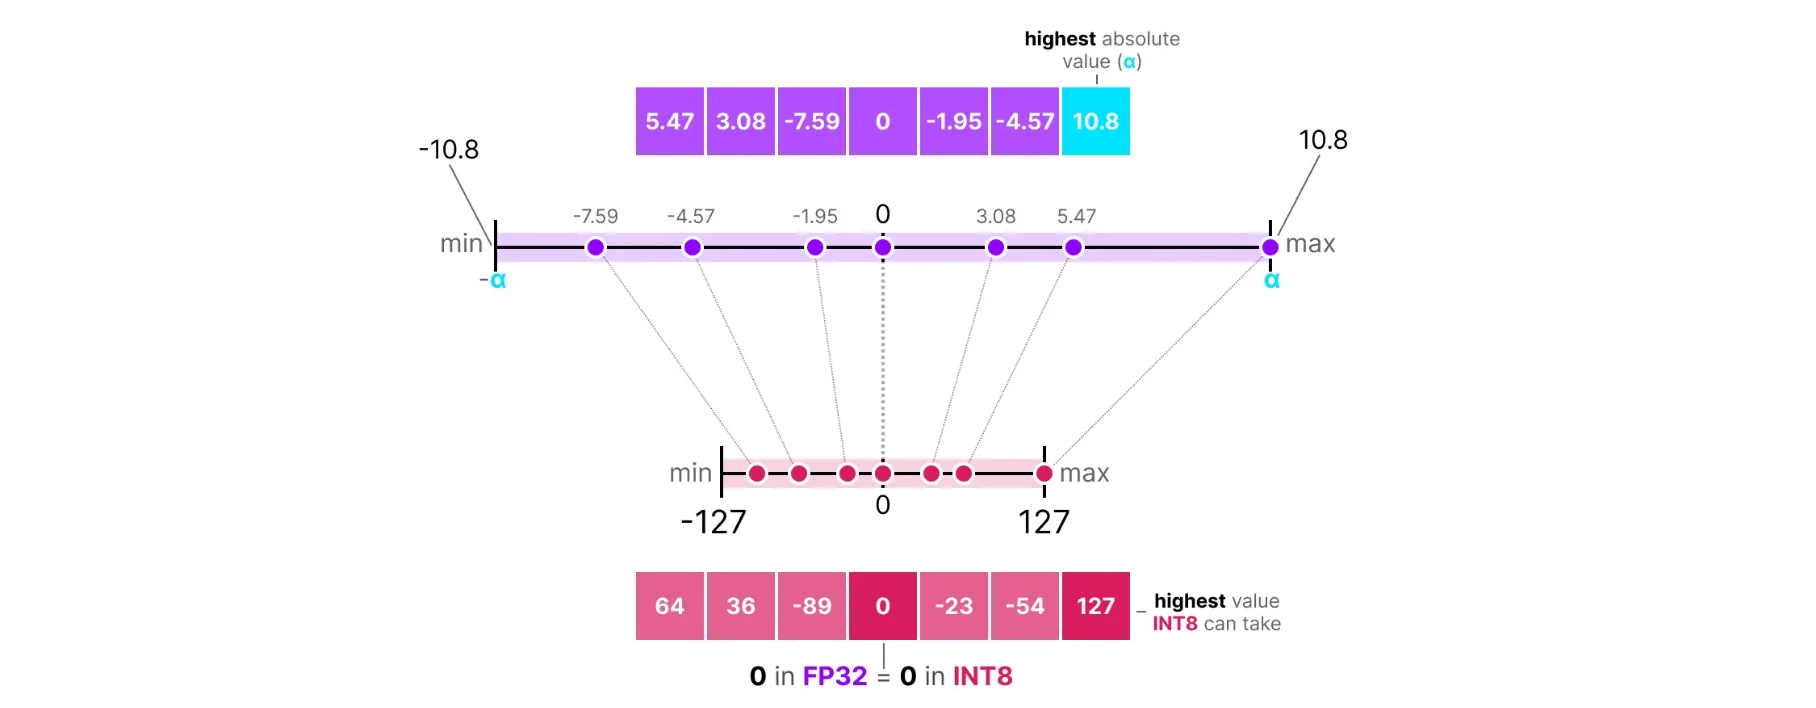
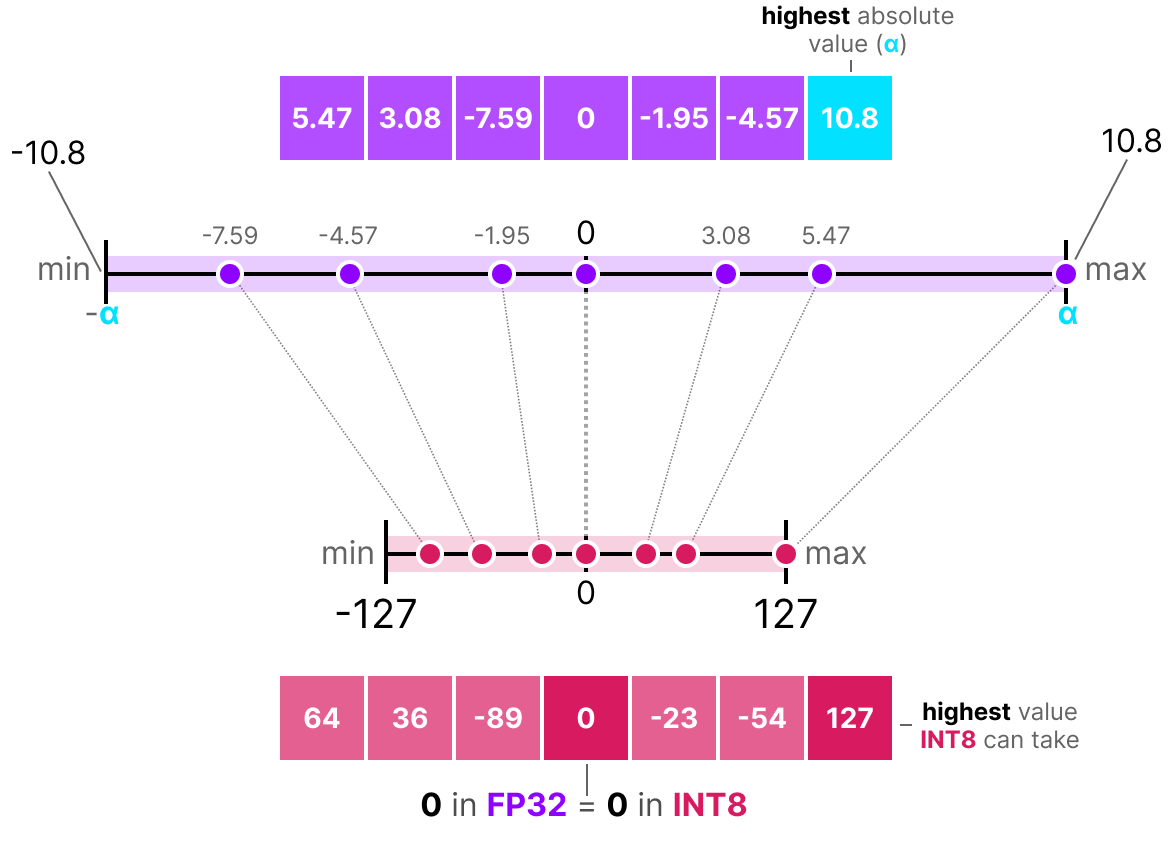
A Visual Guide to Quantization - Maarten Grootendorst
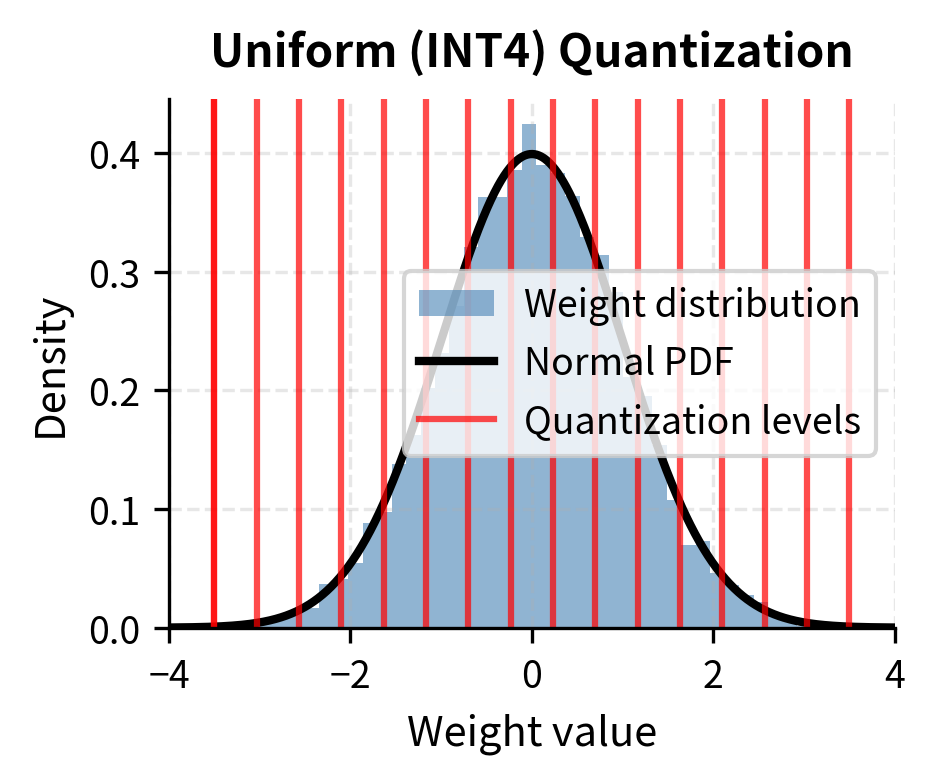
Left: Unsigned INT4 quantization compared to unsigned FP4 2M2E ...
Improving LLM Inference Latency on CPUs with Model Quantization ...
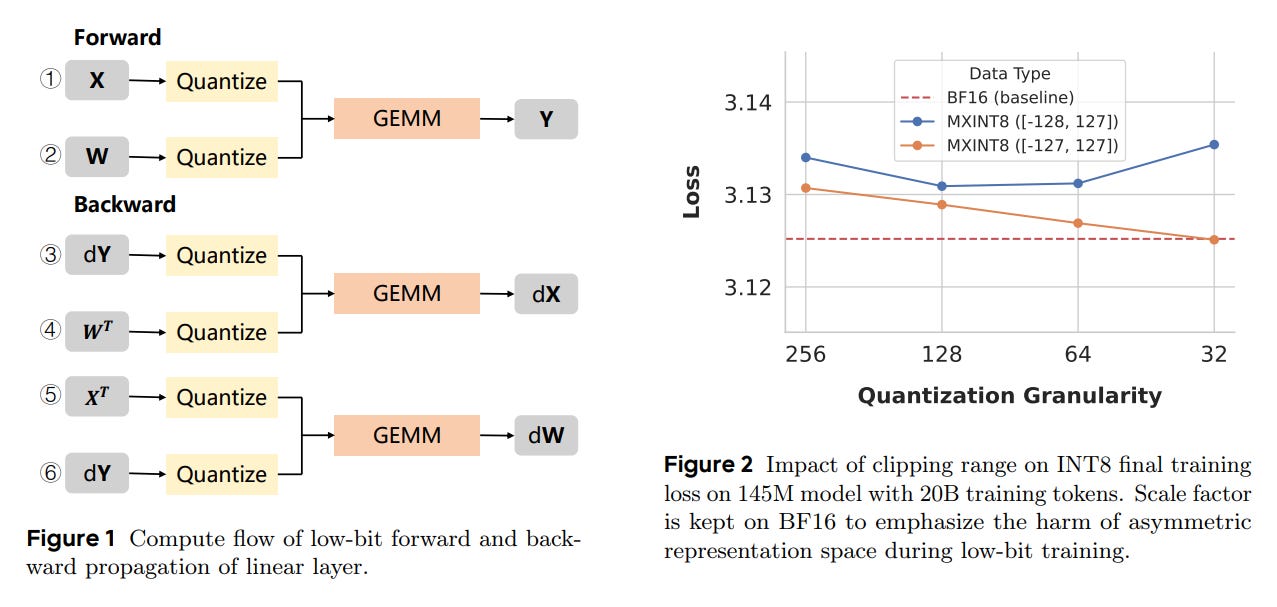
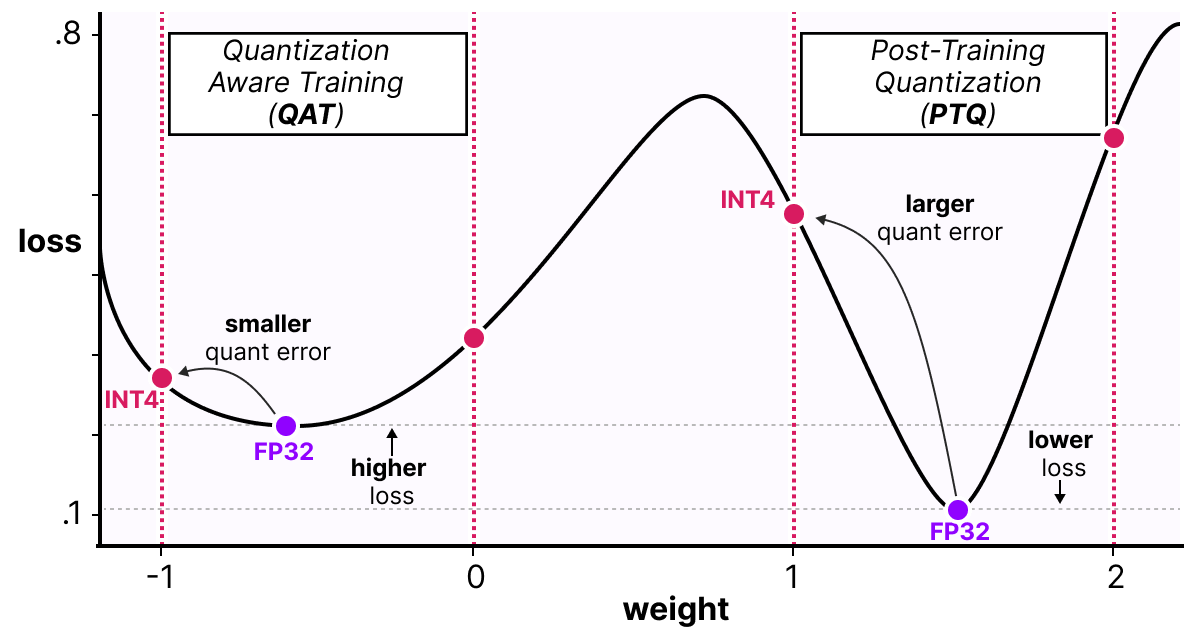
4-Bit Quantization Decoded: INT4 QAT, MXFP4, and NVFP4 — ai.rs
The Quantization Horizon: Navigating the Transition to INT4, FP4, and ...
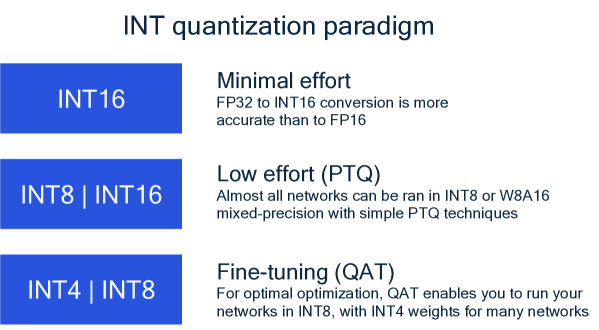
INT8, INT4 and Other Integer Types for Quantization
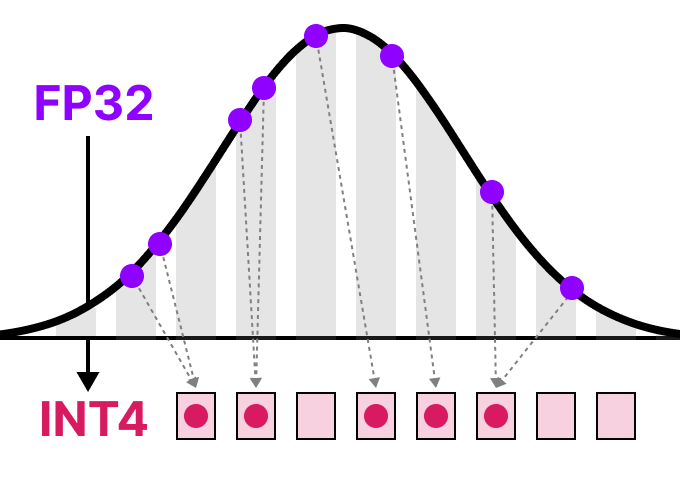
🔢 INT4 vs FP4: The Future of 4-Bit Quantization
[논문 리뷰] INT v.s. FP: A Comprehensive Study of Fine-Grained Low-bit ...
How to optimize large deep learning models using quantization
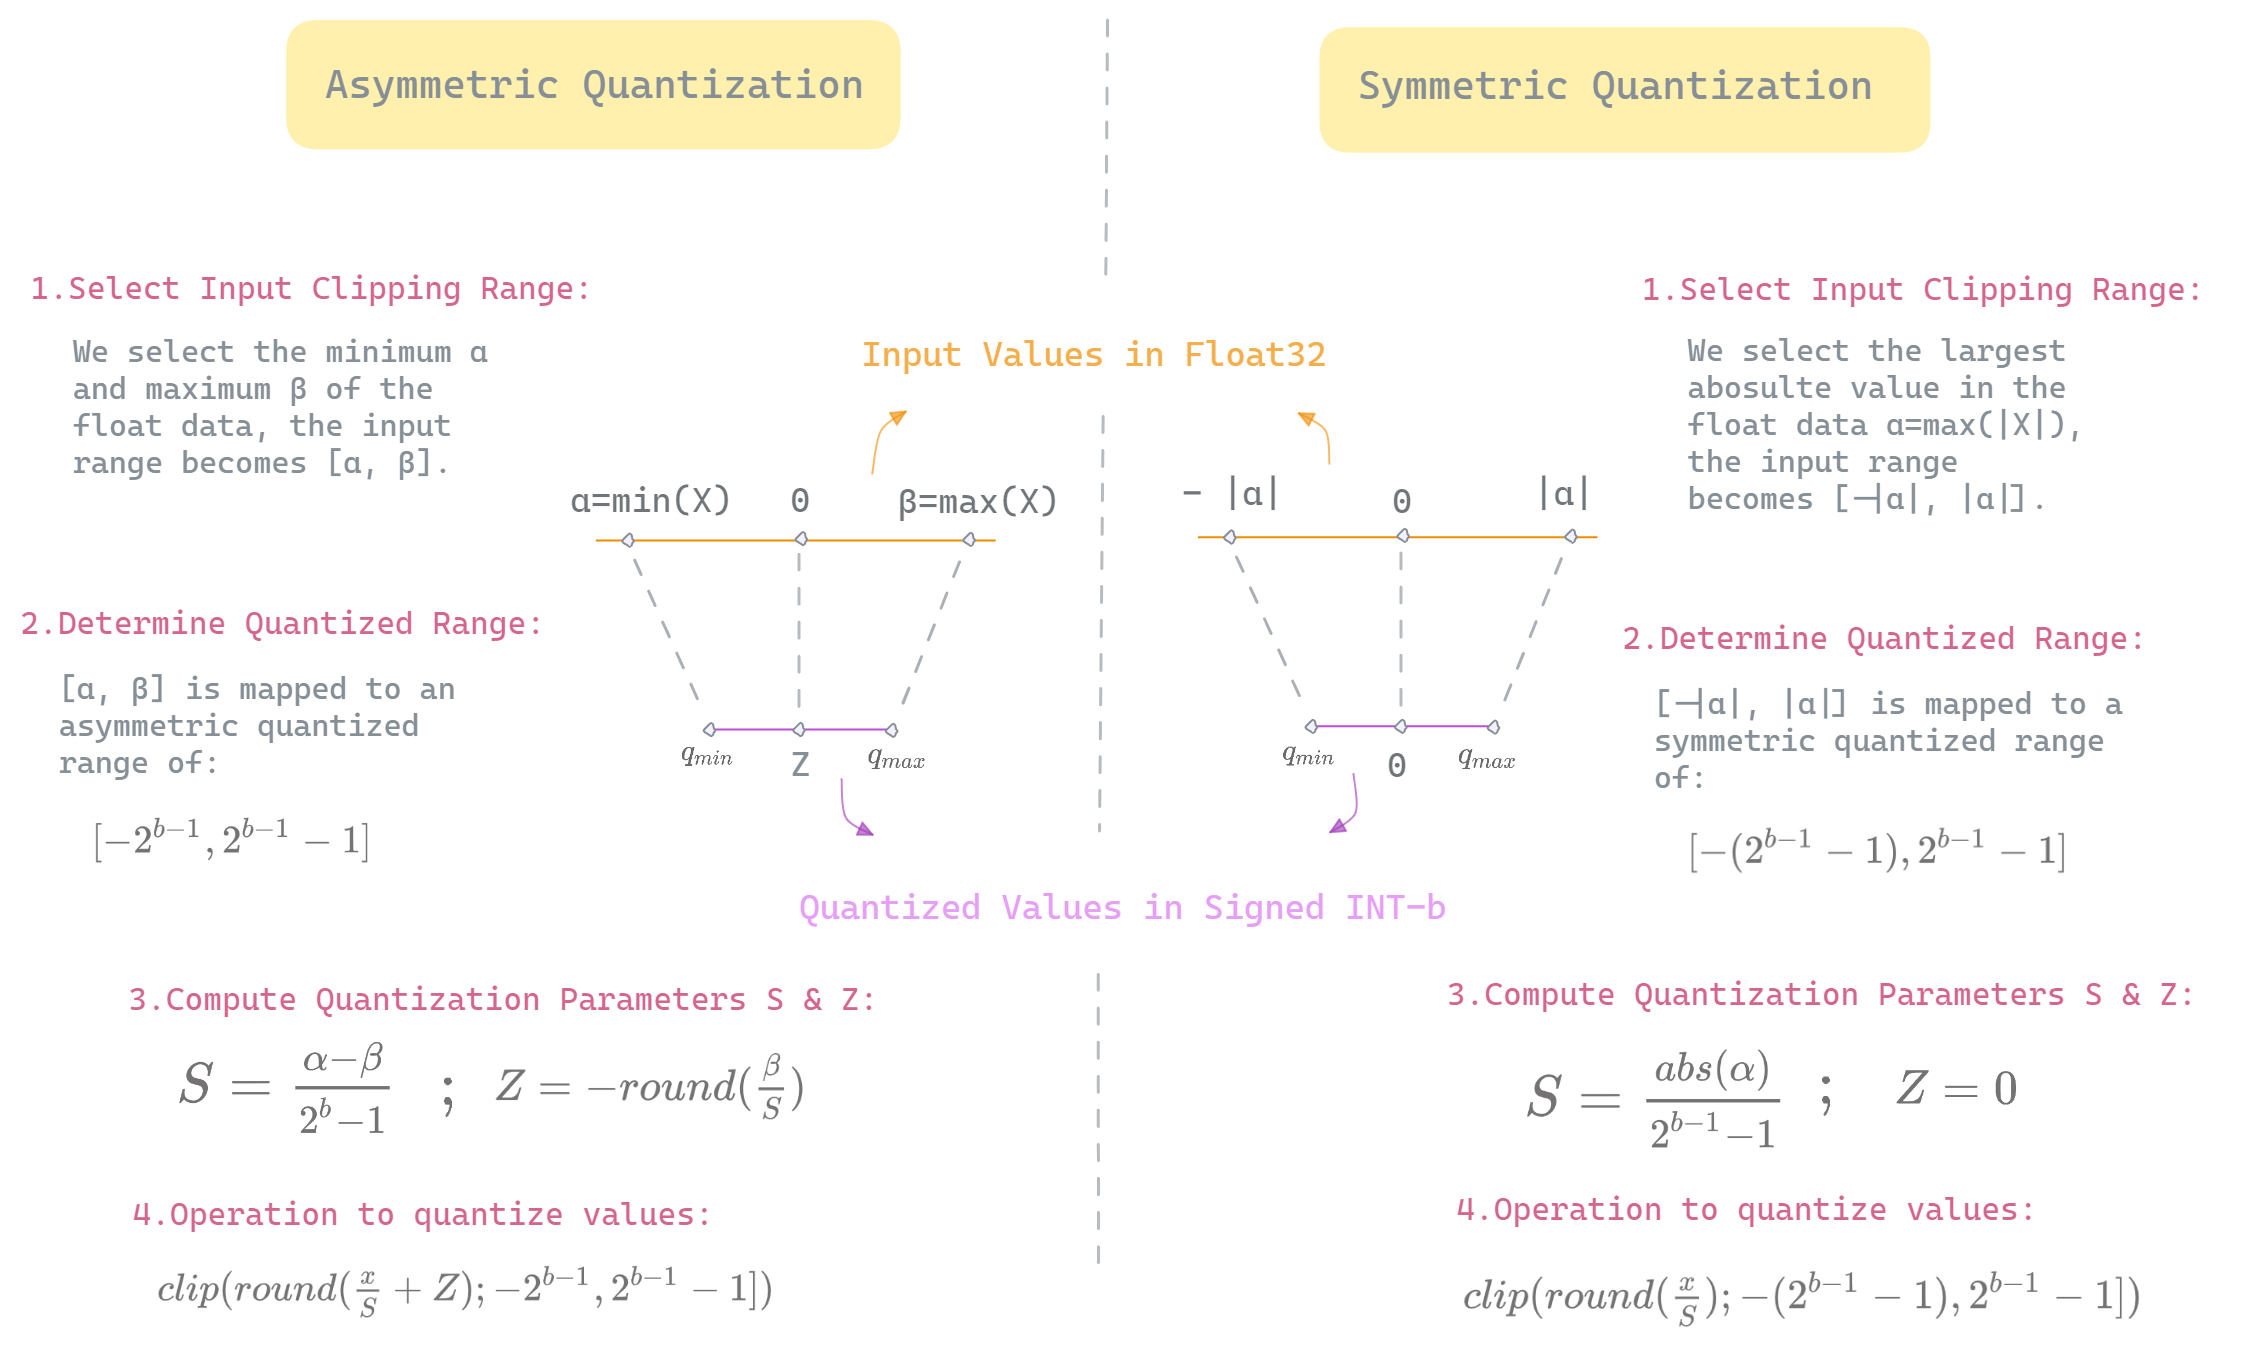
Integer quantization for deep learning inference: principles and ...
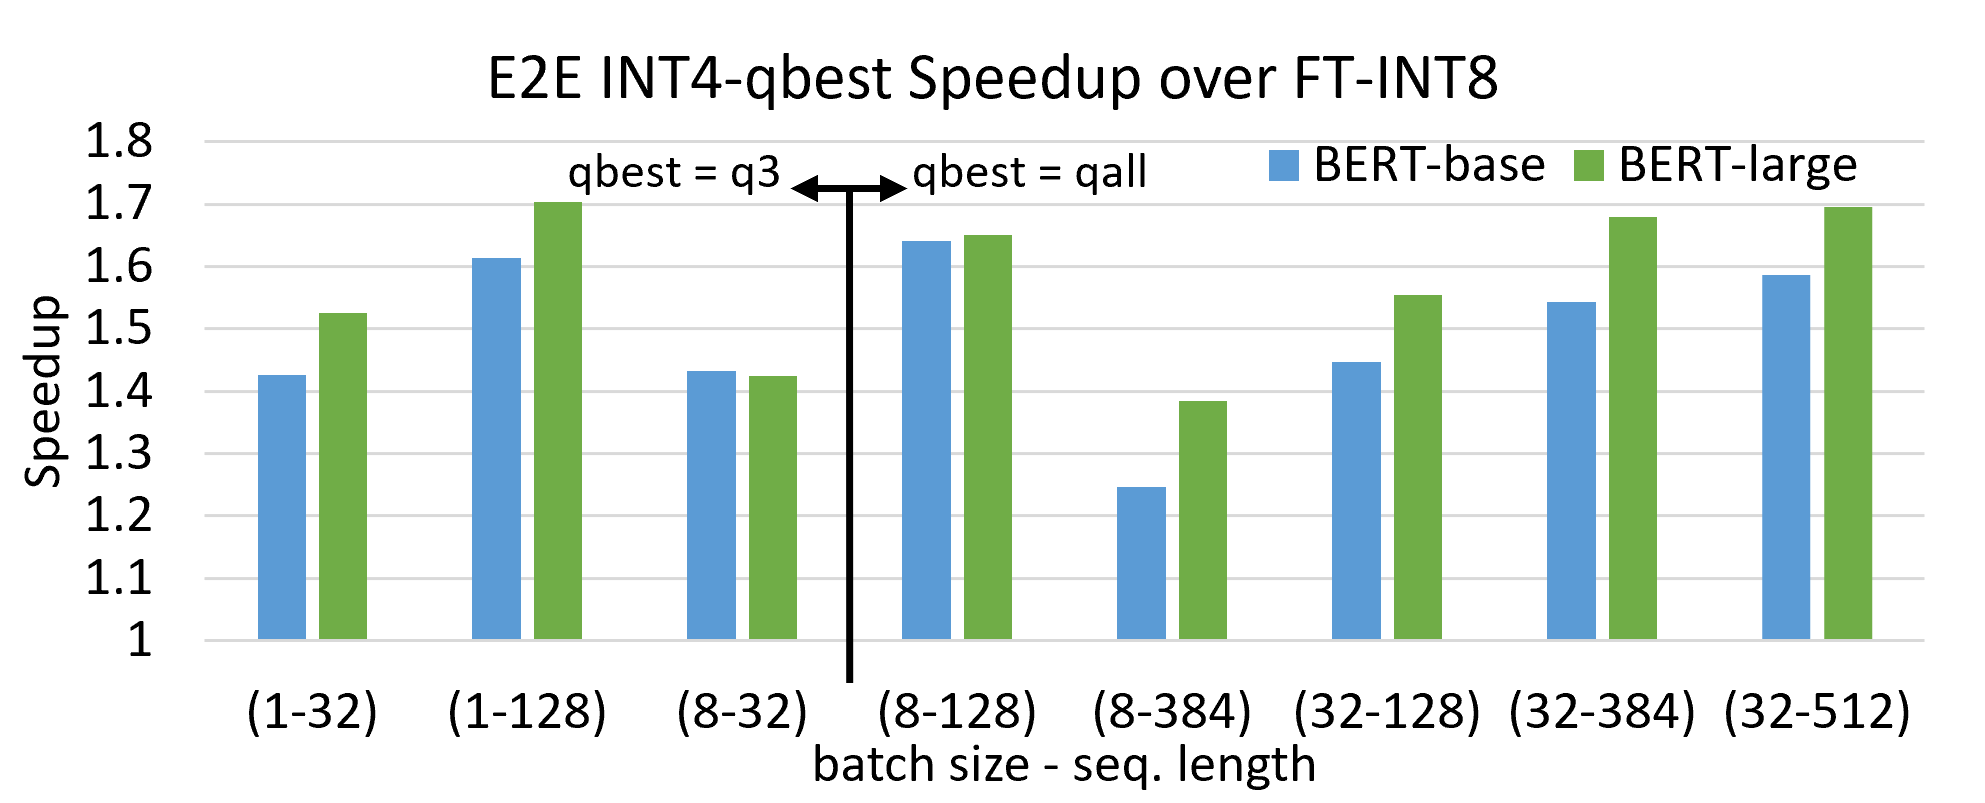
(PDF) Understanding INT4 Quantization for Transformer Models: Latency ...
Mastering QLoRa : A Deep Dive into 4-Bit Quantization and LoRa ...
Quantization Basics — qwix documentation
A Visual Guide to Quantization - by Maarten Grootendorst
LLM Quantization Deep Dive: From FP32 to NF4, INT4, and MX Formats
Quantization for Real Systems — INT4/INT8 Deploy | tutorialQ
14. Quantization — ECE 386
Training with Quantization (QAT/QT) — qwix documentation
openbmb/MiniCPM-V-2_6-int4 · What method of quantization was used to ...
Extremely Low Bit Transformer Quantization for On-Device NMT | PDF
Quantization Deep Dive: From FP32 to INT4 | Abhik Sarkar
Quick Guide to Quantization in Machine Learning
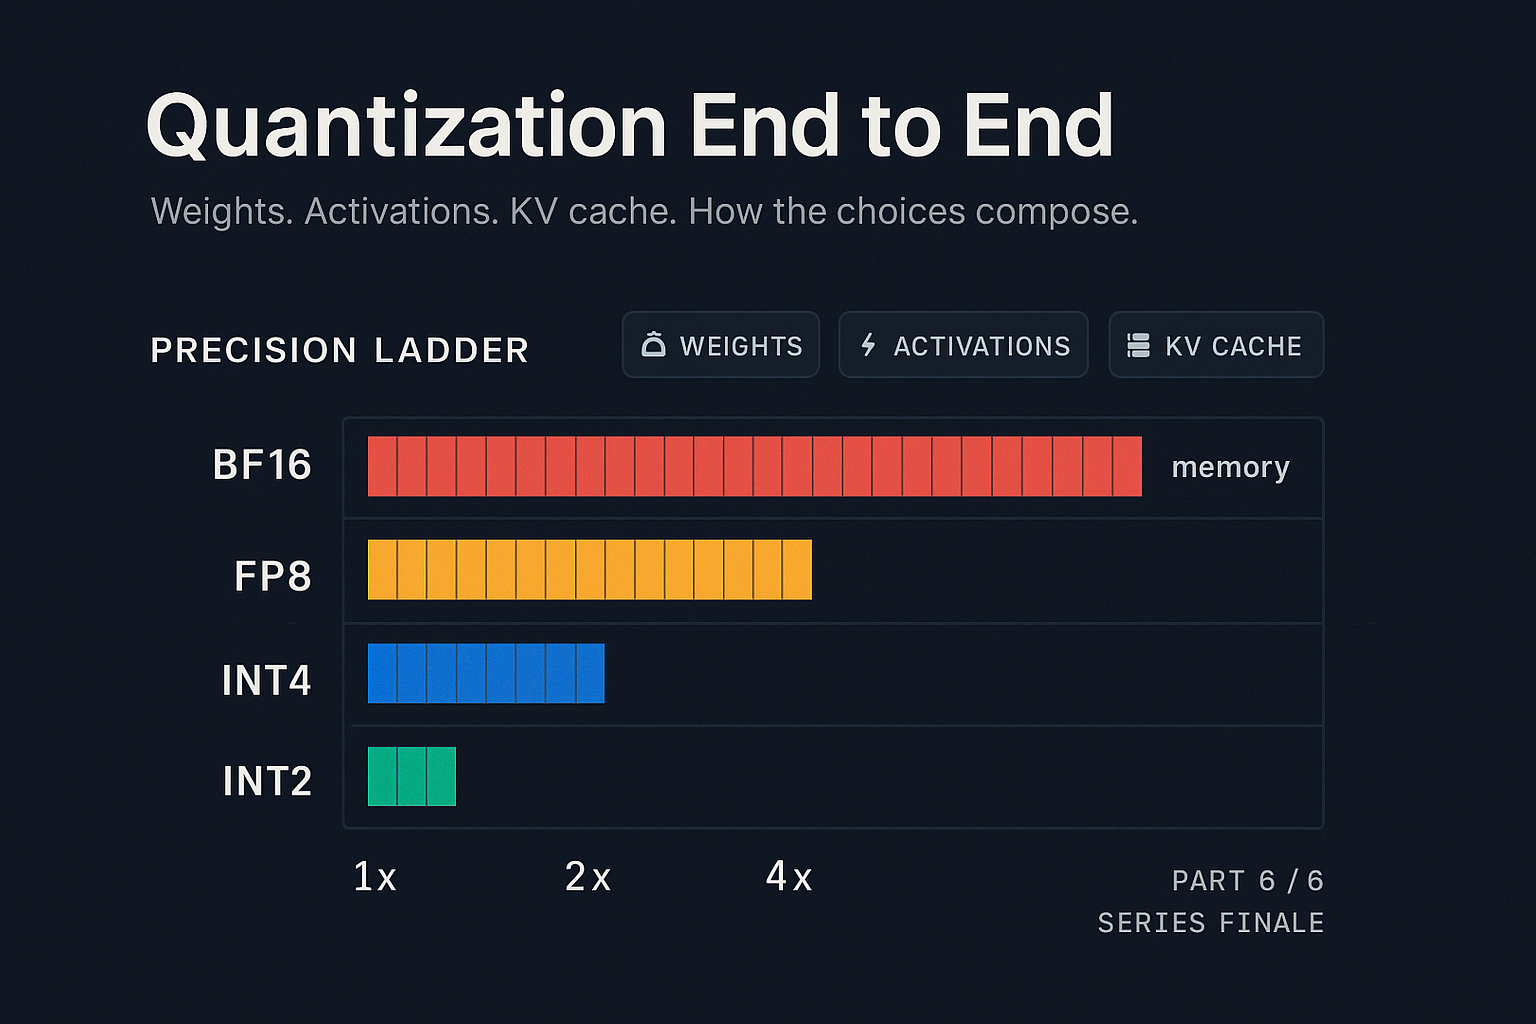
Quantization End to End - Part 6 of 6 - Strongly.AI
[论文评述] When Flat Minima Fail: Characterizing INT4 Quantization Collapse ...
We compare different ways to achieve 4-bit quantization using three ...
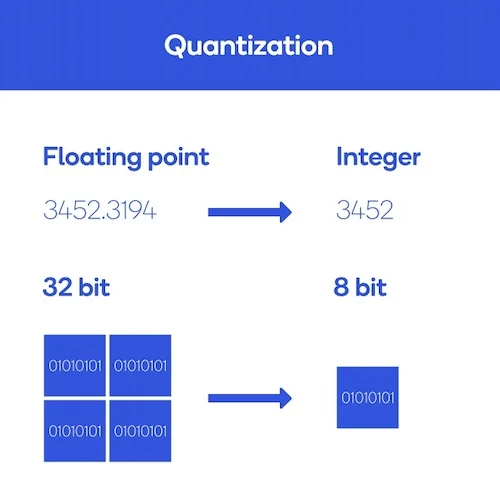
[Deep Learning] 양자화 Quantization - 1. 정의, 사용 경우 및 종류
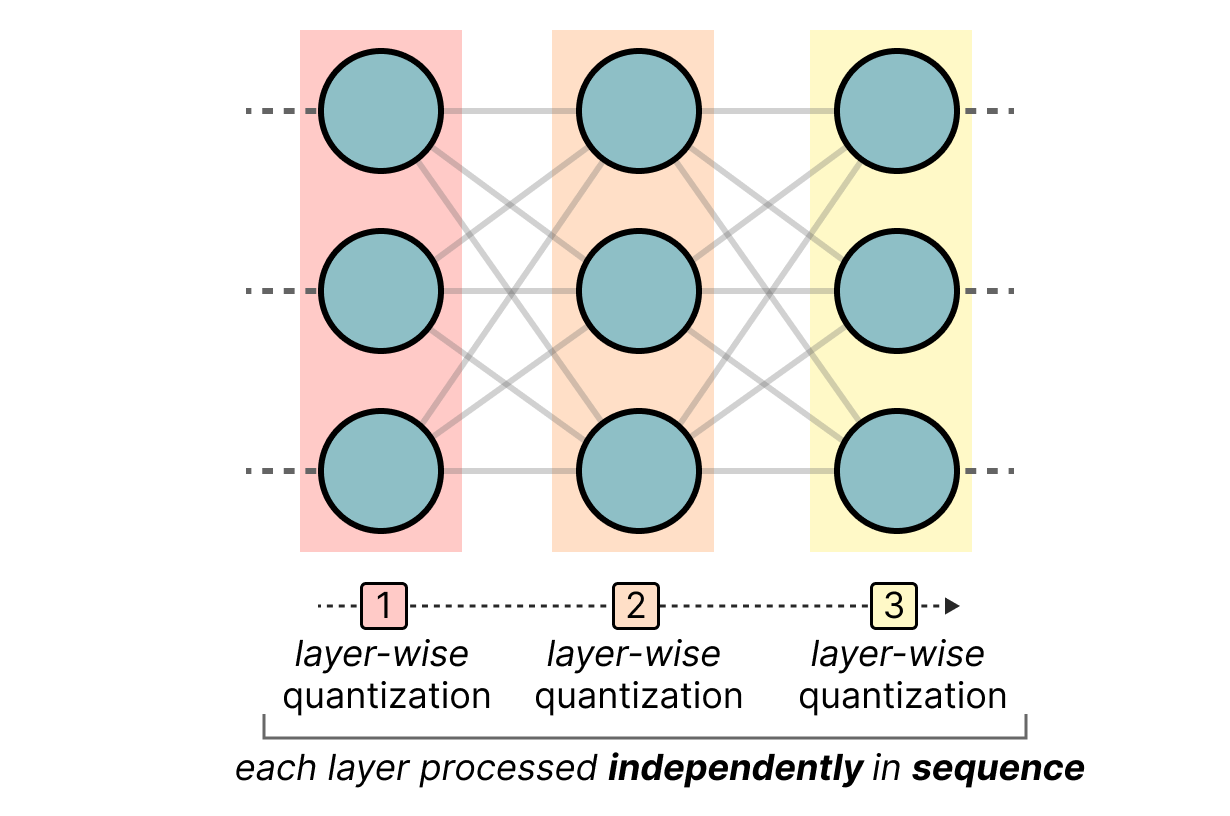
The 4 th one is per-layer quantization, and 5 th is per-channel. AB ...
Quantization and Training of Neural Networks for Efficient Integer ...
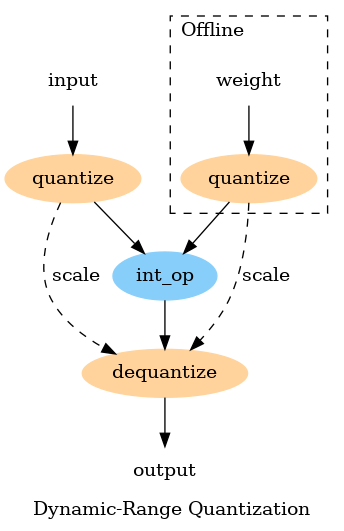
The flow diagram of the Unified Scaling-Based Pure-Integer Quantization ...
[2301.12017] Understanding INT4 Quantization for Language Models ...
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...
Quantization | Mayank Kumar Pal
phase quantization a) four bit quantization b) Three bit quantization ...
int4 Weight Quantization - LLM Compressor Docs
LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI
top-1 accuracy of fp32, Tensorflow's INT4-8 and AB INT4- 4 ...
The Ultimate Handbook for LLM Quantization | Towards Data Science
[논문 리뷰] When Quantization Is Free: An int4 KV Cache That Outruns fp16 ...
A conventional integer quantization architecture for inference and the ...
FPGA-Based Implementation and Quantization of Convolutional Neural ...
Quantization — Intel® Extension for Transformers 0.1.dev1+g087056c ...
A Survey On Neural Network Quantization | Proceedings of the 2025 6th ...
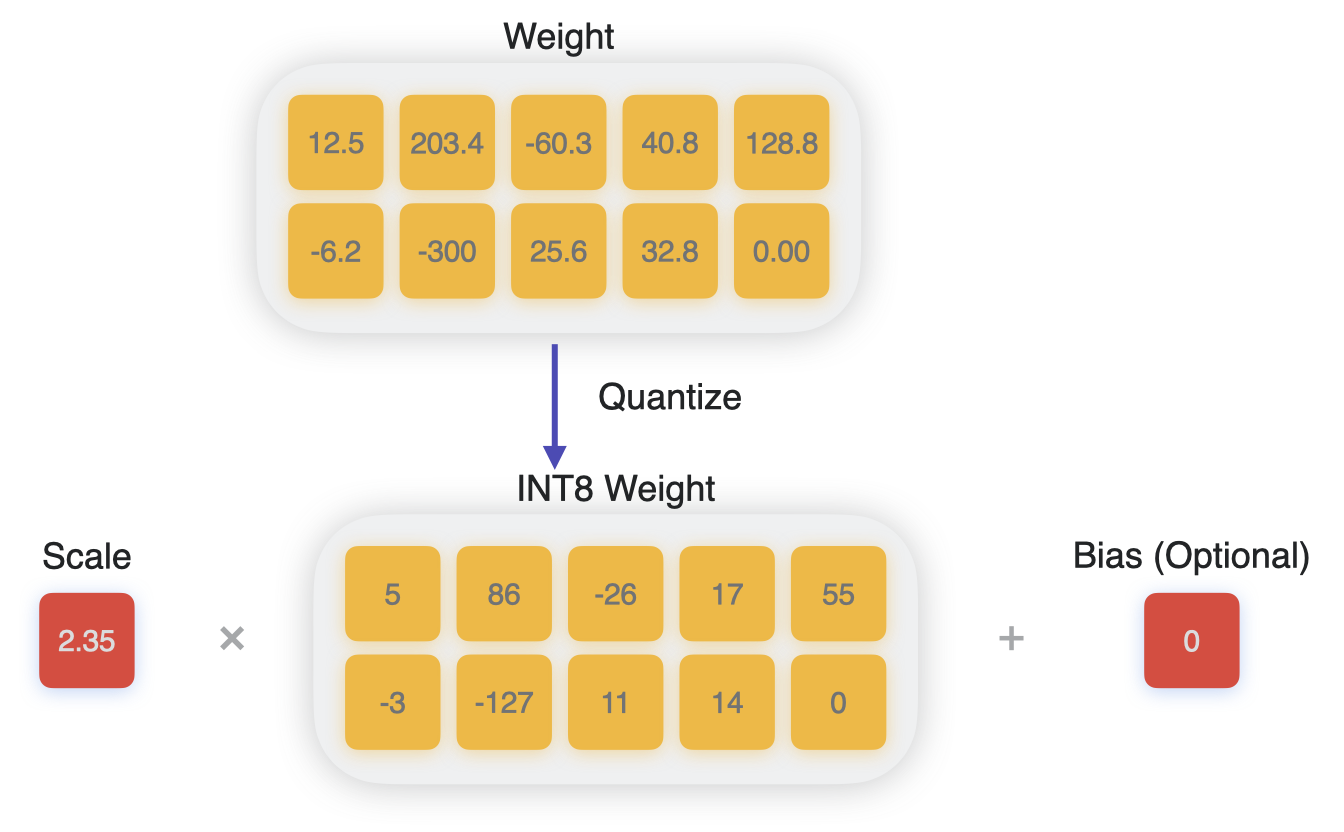
Introduction to Weight Quantization | Towards Data Science
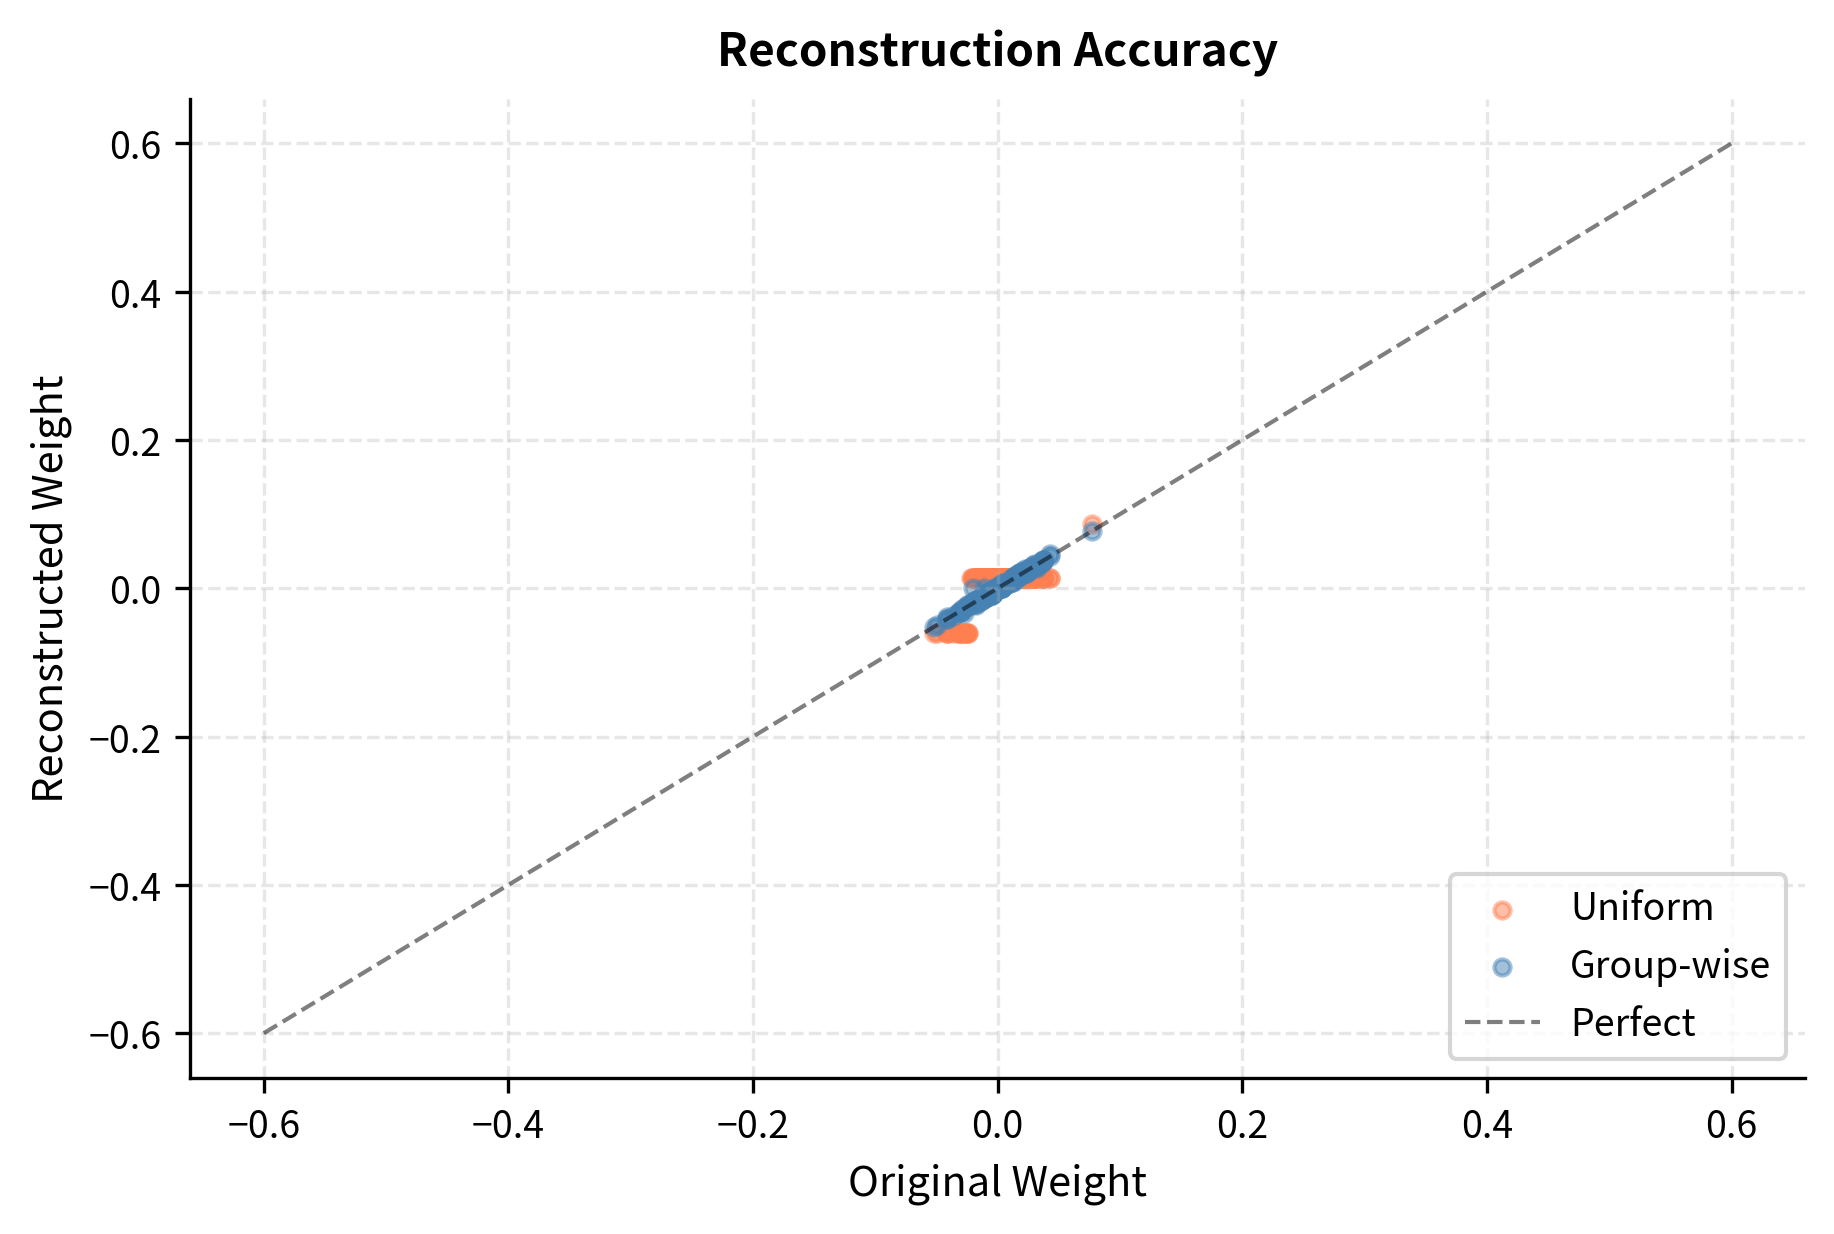
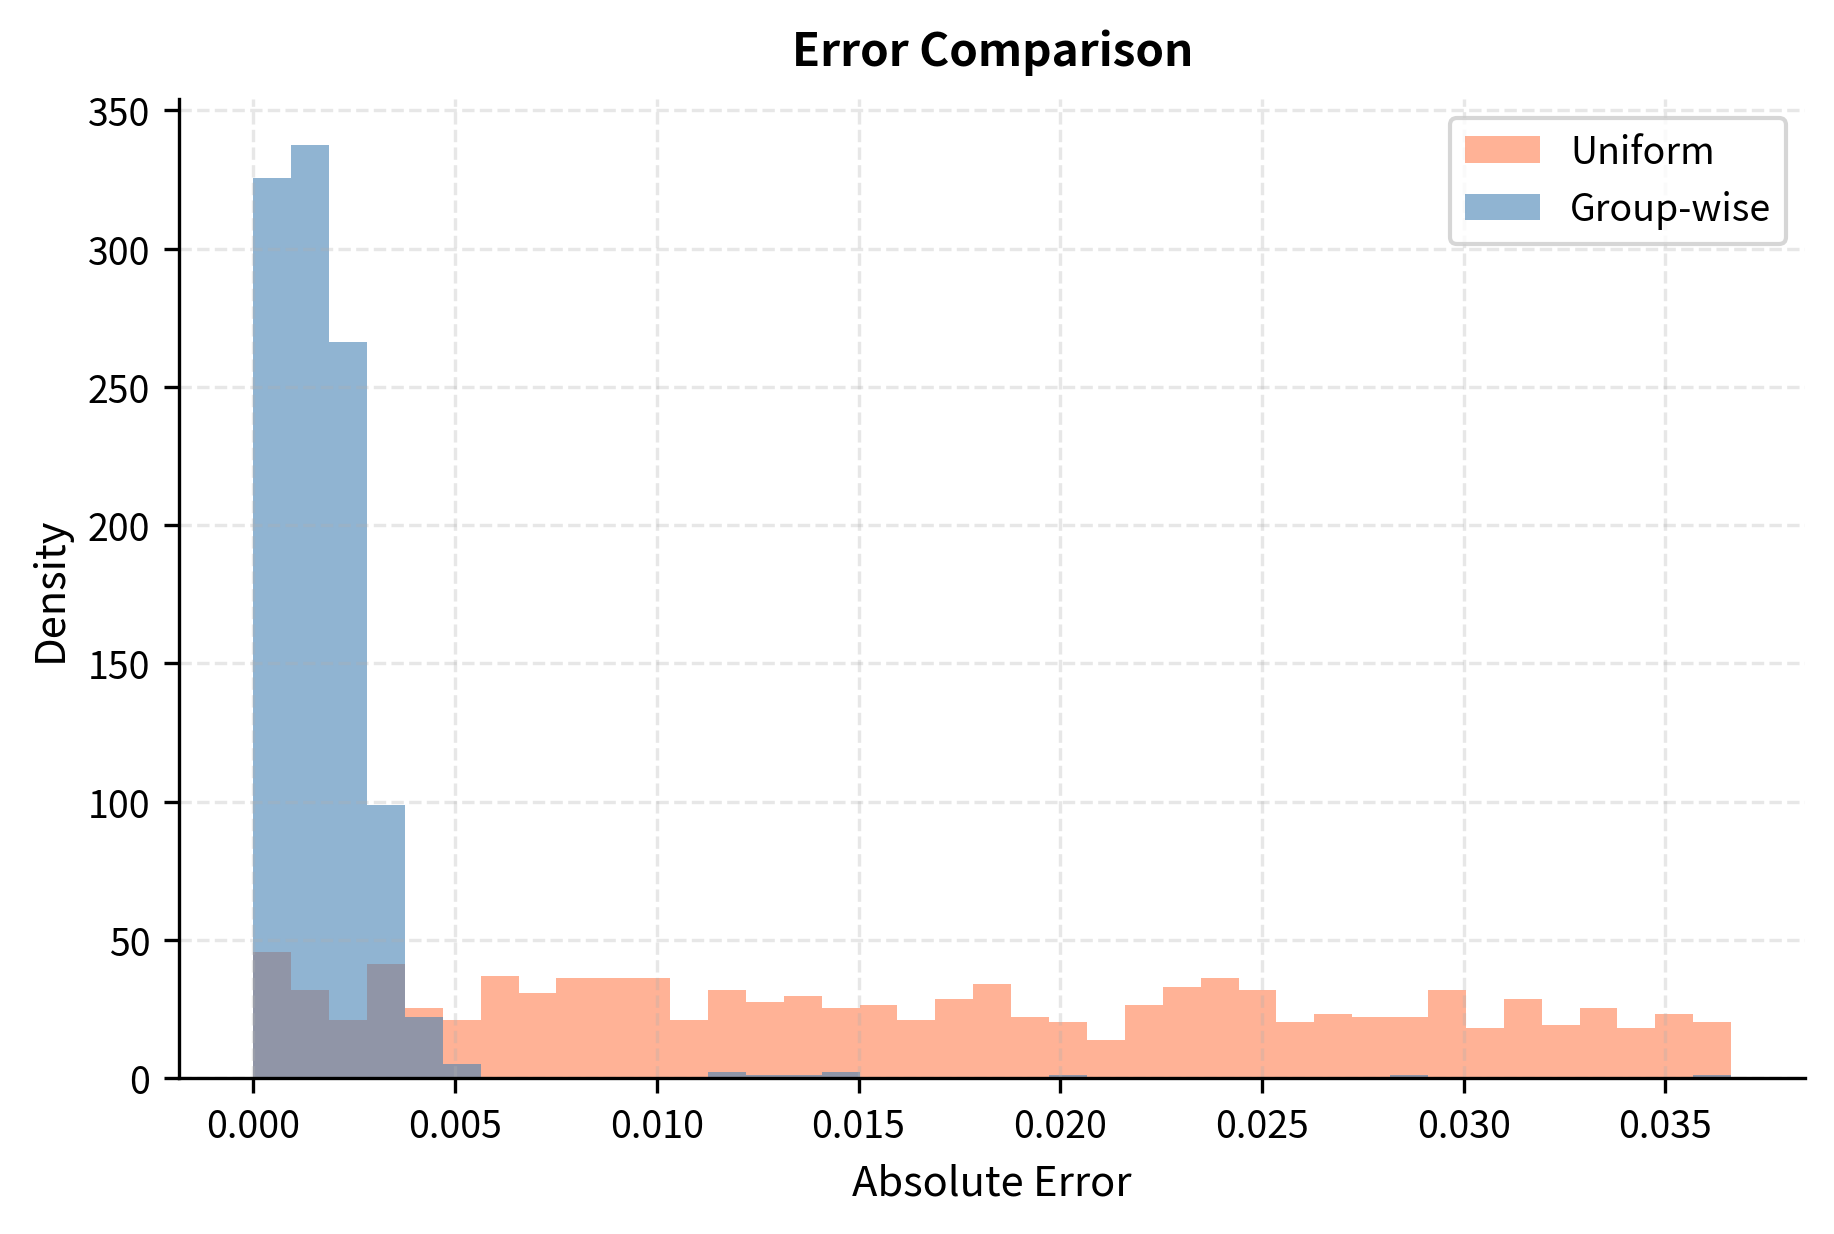
INT4 Quantization: Group-wise Methods & NF4 Format for LLMs ...
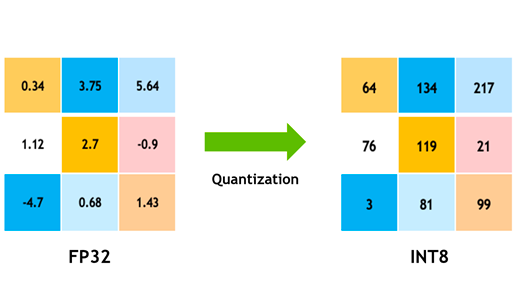
What Is Quantization? FP32-to-INT4 for LLMs
INT4 Decoding GQA CUDA Optimizations for LLM Inference – PyTorch
Simplified diagrams showing the computation flows for (a) the ...
Hardware acceleration and matrix multiplication mechanisms for INT4 ...
Floating-point arithmetic for AI inference — hit or miss? | Qualcomm
TurboQuant vs 기존 AI 압축 기술
在至强(Xeon)平台上借助 🤗 Optimum Intel 加速 StarCoder:Q8/Q4 和推测解码 - Hugging Face 文档
Mixed-precision Interpolative Decomposition on GPUs | Proceedings of ...
INT4, INT8, and When Accuracy Actually Drops | Luca Berton
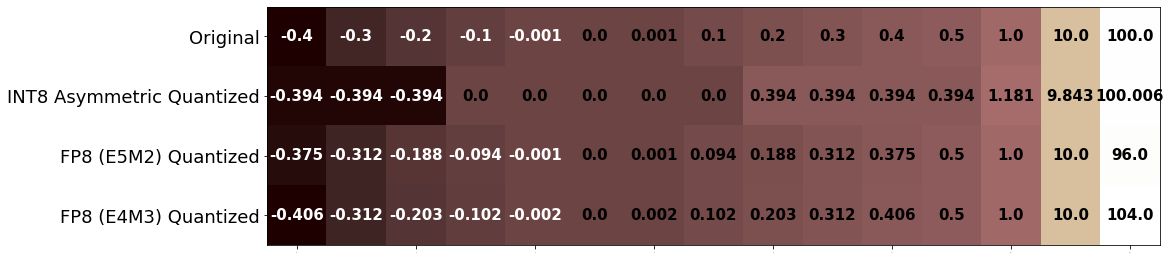
[2303.17951] FP8 versus INT8 for efficient deep learning inference
Quark Quantized INT4 Models - a amd Collection
Full Integer Quantization. | Download Scientific Diagram
(PDF) FP8 versus INT8 for efficient deep learning inference
#1 - Getting Started - No BS Intro To Developing with LLMs | GDCorner
Quark Quantized INT4 ONNX Models - a amd Collection
zai-org/glm-4v-9b · How to run the Int4 quantized model?
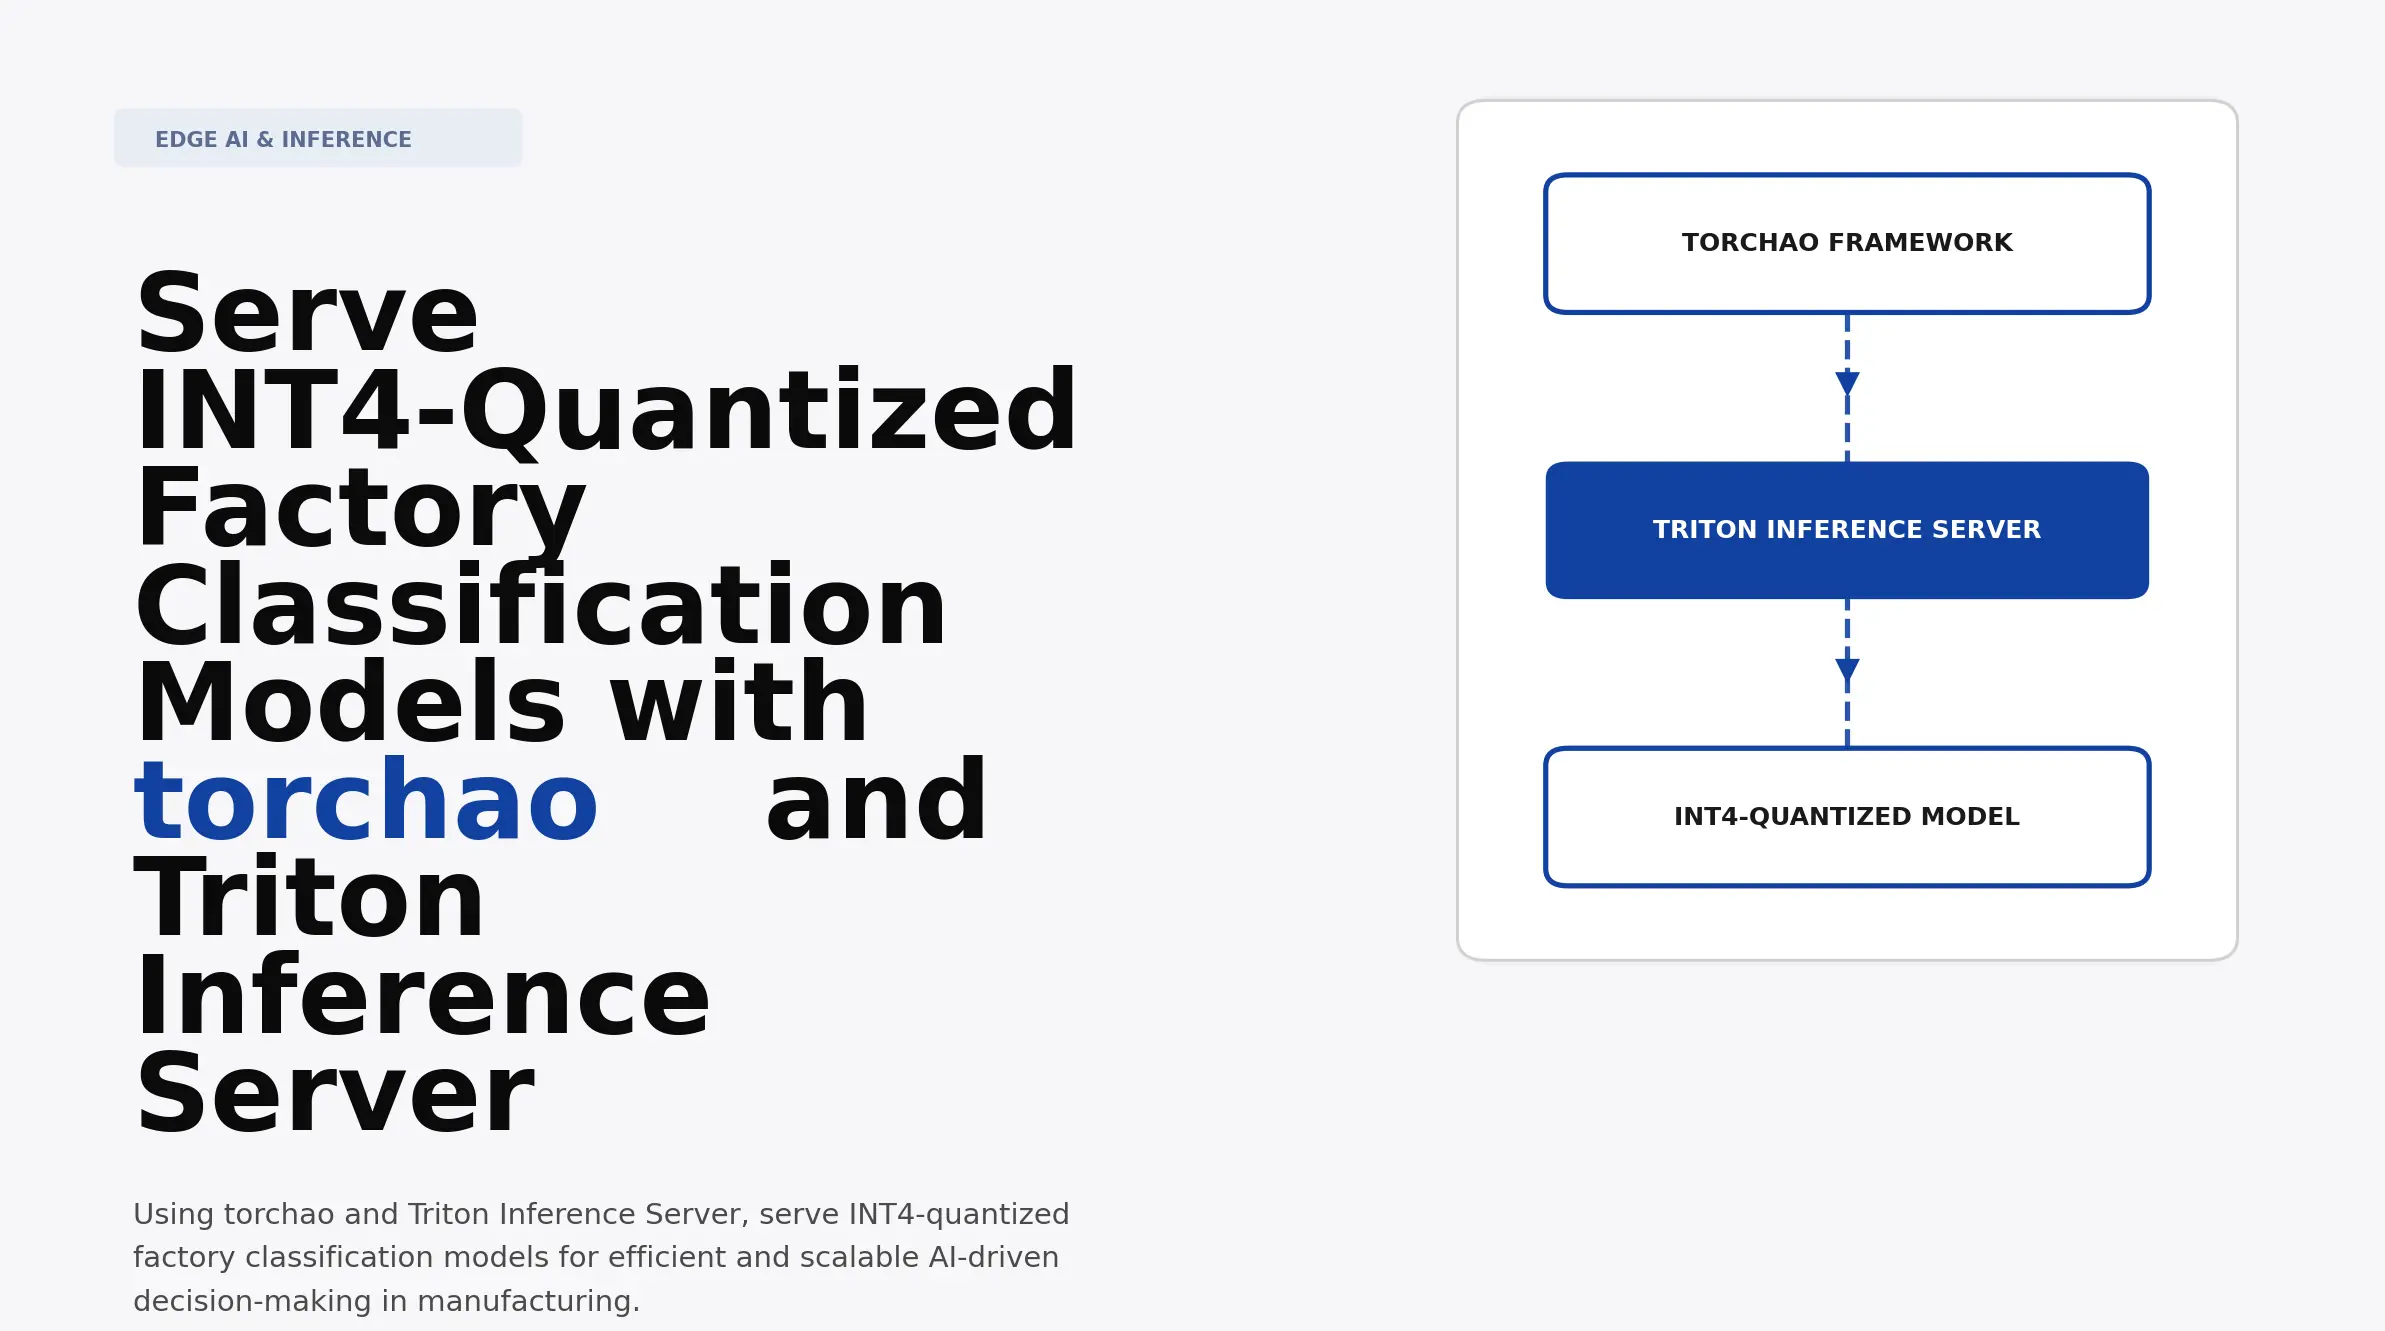
Serve INT4-Quantized Factory Classification Models with torchao and ...
[论文评述] Q-GaLore: Quantized GaLore with INT4 Projection and Layer ...
Cost Optimization in LLM Hosting | AI Tutorial | Next Electronics
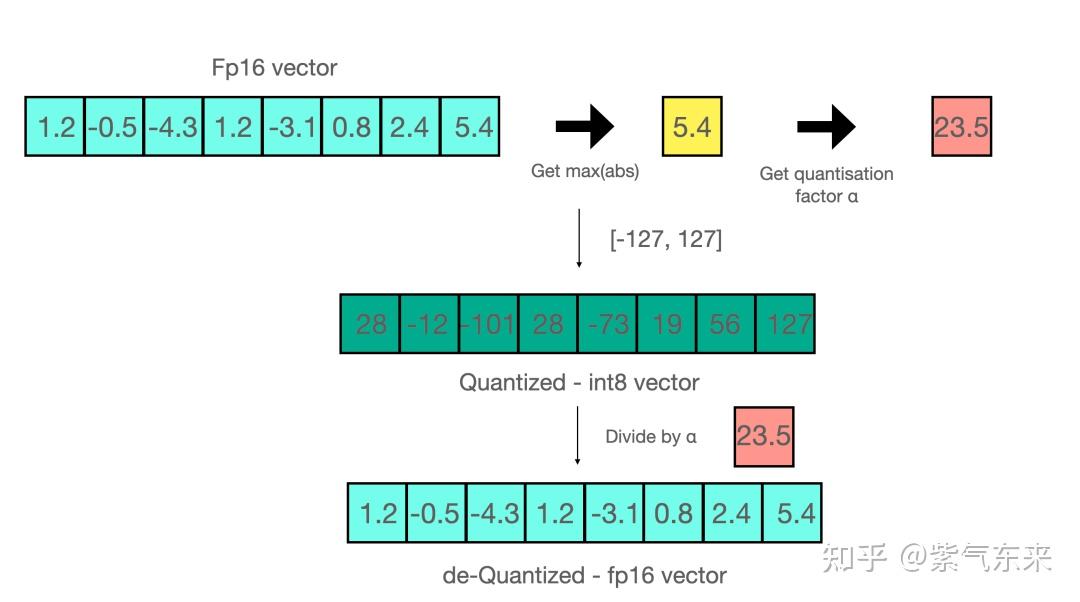
LLM(11):大语言模型的模型量化(INT8/INT4)技术 - 知乎
ML Blog - Technical Blog on Machine Learning
Looper Quantize Questions? | Loopers! Why is quantize not standard ...
Int4 Precision for AI Inference | NVIDIA Technical Blog
jnjj/gemma-3-4b-it-qat-int4-quantized-inference-unrestricted-weights ...
google/gemma-3-4b-it-qat-int4-unquantized · Hugging Face
[2307.09782] ZeroQuant-FP: A Leap Forward in LLMs Post-Training W4A8 ...
Topic: int4-quantization | AINews
Model Quantization: Tối Ưu Hóa Hiệu Năng Mô Hình AI
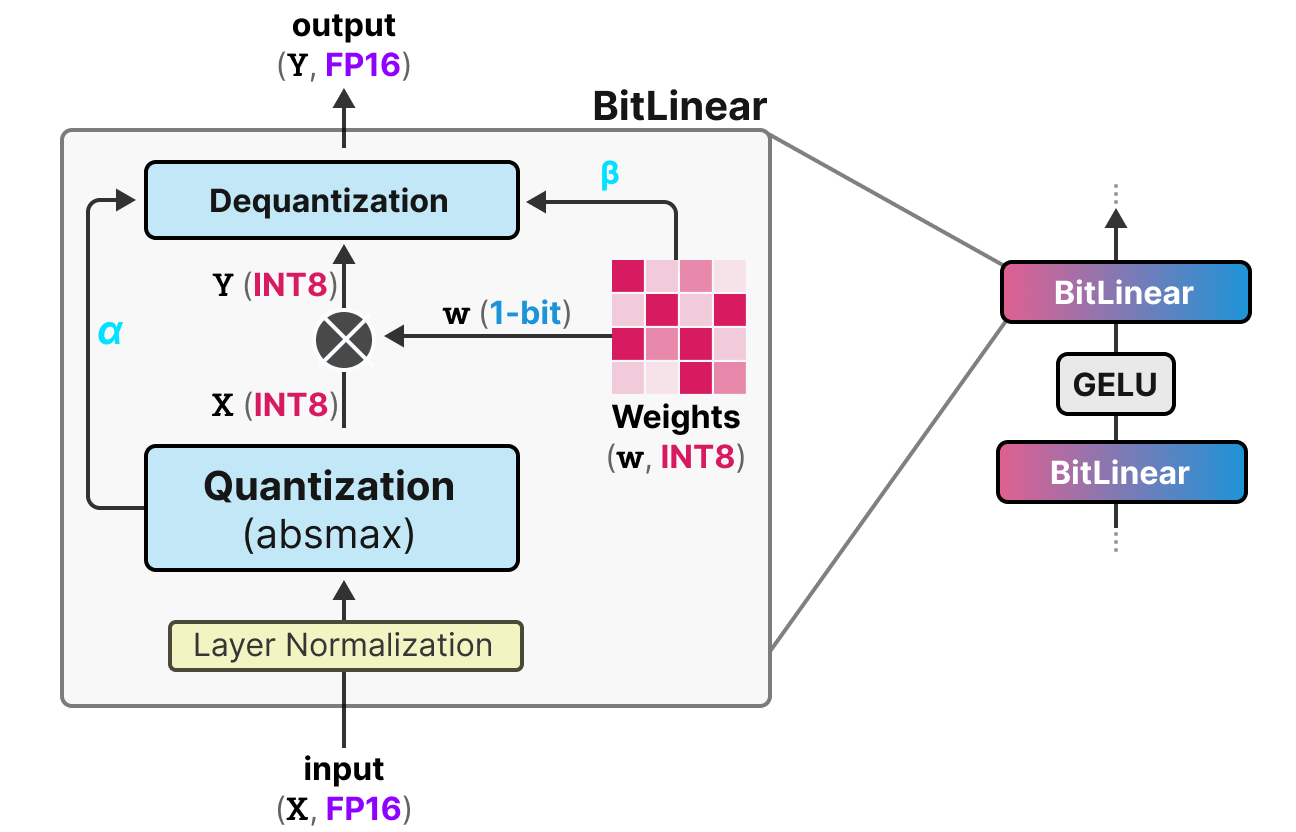
50张图解密大模型量化技术:INT4、INT8、FP32、FP16、GPTQ、GGUF、BitNet_gptq量化-CSDN博客
[Fundamental] 模型量化 | Ubios Home
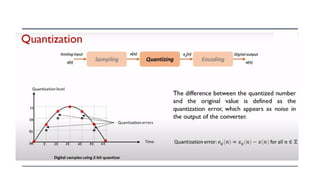
What Is Quantization? Understanding Digital Signal Conversion ...
any4: Learned 4-bit Numeric Representation for LLMs | AI Research Paper ...
Integer Quantization: Deep Dive 🤿
Quantized 8-bit LLM training and inference using bitsandbytes on AMD ...
pe-nlp/deepseek-pt-v3-quantized-int4 at main